In short
What it measures
the time to first byte (TTFB) and the HTTP protocol version your server responds with.
Thresholds
0.8 seconds or less is good and more than 1.8 seconds is poor, according to web.dev.
Why it matters
TTFB comes before any other loading metric; what’s lost here can’t be recovered.
Wakaris data
38.2% of the pages analyzed fail this finding.
What this finding is and what it measures
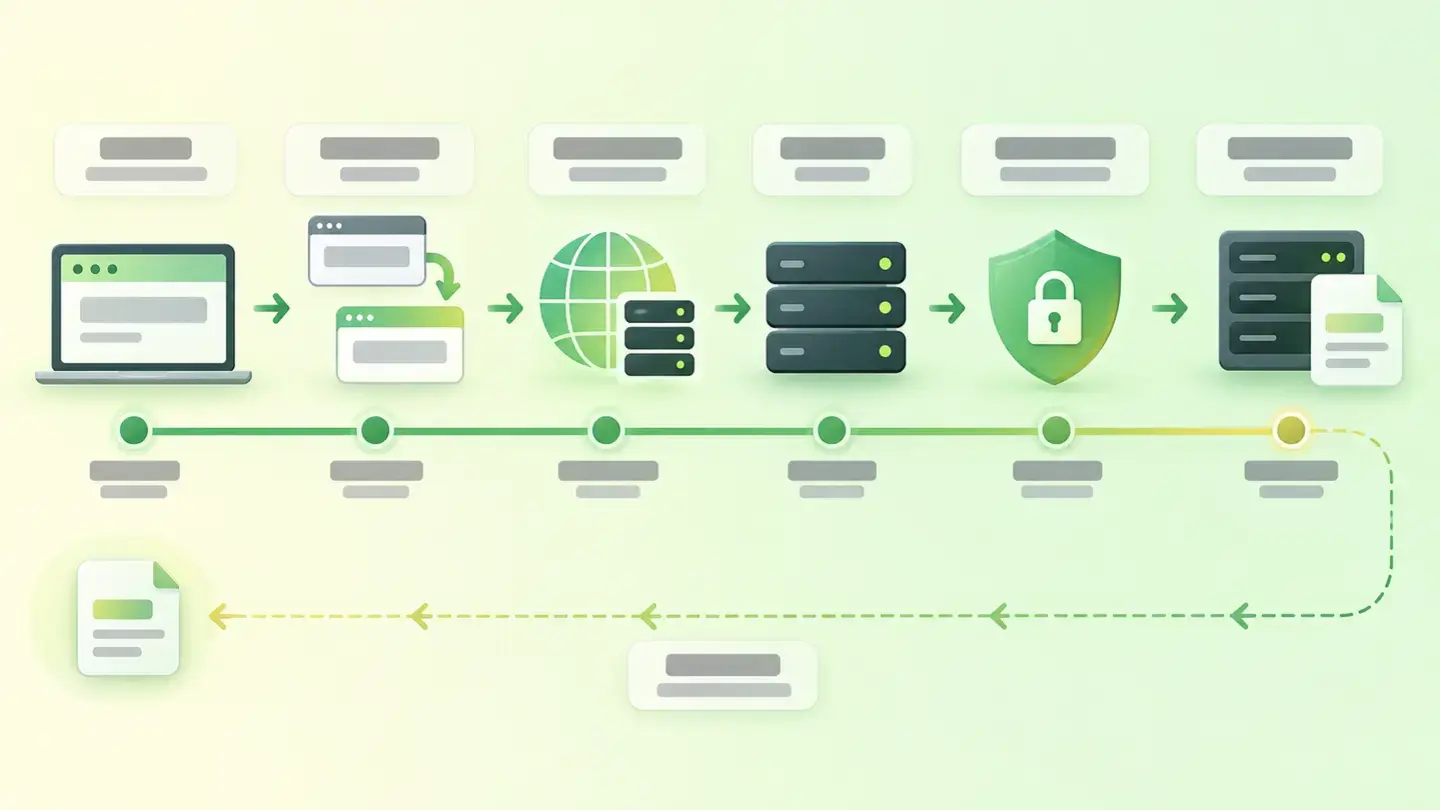
The name combines two different questions. The first is how long you take to respond: that’s TTFB, the time between when the browser starts navigating to the page and when the first byte of the response starts to arrive. The second is how you deliver what you respond with: which version of the HTTP protocol your page travels on.
TTFB isn’t a single thing, and that’s why it’s confusing. According to web.dev, it includes redirect time, service worker startup if there is one, the DNS lookup, establishing the connection and TLS negotiation, and the request itself until that first byte arrives. Almost none of that has to do with how much your page weighs.
The second part checks whether delivery uses a protocol version that’s already considered old. A server that responds with HTTP/1.1 forces the browser to work within the limitations of a 1990s design, while later versions were created precisely to remove them.
How it’s measured
Wakaris measures TTFB by loading your URL and timing from the start of navigation to the first byte, and also records the protocol version the server responded with. It gives you both pieces of evidence together, without installing anything or creating an account, and that’s the direct way to know where you stand.
The thresholds aren’t made up. web.dev sets good TTFB values at 0.8 seconds or less and poor ones above 1.8 seconds, and those are exactly the two cut-offs the finding applies: above 800 milliseconds there’s a warning, and above 1,800 the case is serious.
There’s an honest nuance worth knowing. Those reference thresholds are defined on the 75th percentile of your visitors’ real page loads; a check like this one measures a specific load from a specific location, so what you get is a lab reading against a bar designed for field data. It works perfectly for spotting a slow server and checking whether a fix worked, but a value right at the boundary is worth measuring several times before calling it good or bad.
Why it matters
TTFB matters because of its place in the queue, not its own weight. web.dev is explicit in both directions: TTFB isn’t a Core Web Vitals metric and meeting its threshold isn’t essential, but it precedes every other meaningful loading metric. Put simply: every tenth of a second you lose waiting for the first byte is a tenth you can no longer recover by optimizing images, compressing text or preloading anything.
The protocol version matters for another reason. RFC 9113 explains that HTTP/1.0 only allowed one outstanding request at a time per connection, and that the pipelining added in HTTP/1.1 only partially solved concurrency and still suffers from head-of-line blocking. HTTP/2 addresses that by allowing messages to be interleaved on the same connection, encoding headers efficiently and allowing requests to be prioritized.
The practical effect is cumulative: a slow server delays the start and an old protocol chokes everything that comes after.
Common causes
The causes of high TTFB fall into two halves, and telling them apart is what decides the fix.
The first half happens before your server knows anything: chained redirects, each adding a full round trip; a slow DNS lookup; and the cost of opening the connection and negotiating encryption, which grows with the physical distance between your visitor and your server. If you sell in one country and host on another continent, this half is already costing you money.
The second half is your server thinking: database queries without indexes, a page generated from scratch on every visit instead of being served ready-made, an overloaded shared hosting plan, or processes added by extensions and plugins that run before the first line is returned.
With the protocol, the cause isn’t technical: nobody has touched it. Many server configurations still serve over HTTP/1.1 because that’s how they came and it works. Here’s a clue: if your website spreads resources across several subdomains to get around the parallel connection limit, that trick dates from the HTTP/1.x era and today works against you.
How to fix it
Order matters, because the two halves don’t cost the same.
Start with what’s free: remove unnecessary redirects. Each hop is a round trip before anything starts, and internal links pointing to an address that redirects are the easiest case to fix.
Next, distance. If your visitors are far from your server, bringing the response closer (with a content delivery network or by moving your hosting) tackles DNS, connection and TLS all at once. It’s the lever with the best effort-to-result ratio when your market and your server don’t match.
Then stop generating what doesn’t change. Caching the response on the server turns a computed page into a served page, and that’s where whole seconds drop off.
Turn on a modern version of the protocol. On most servers and control panels it’s a checkbox or a configuration line, not a migration, and if you had resources spread across subdomains, bring them back together. And when you’re done, run the page through Wakaris again: TTFB is one of the few metrics where you see the before and after on the first try.
Ask your AI
These two prompts are designed to be pasted as is into your AI assistant. Pick the one that matches your situation: the first if you’ve already measured your website and want to lower the response time; the second if you got here without measuring anything and want to know if it affects you.
I already have the finding measured with Wakaris and want to fix it
Act as a professional, careful technical web analyst. Your goal is to help me understand a specific finding about my website and decide what to do about it, without making anything up.

Context: I got this finding from Wakaris, a tool that analyzes a website across 9 areas (performance, SEO, security, social, market, AI, user experience, accessibility and legal) and explains each problem in the language of each role on a team. The finding is: Response and delivery. My server takes too long to send the first byte of the response, or delivery uses an old version of the HTTP protocol (reference: a time to first byte of 0.8 seconds or less is considered good, and above 1.8 seconds is poor).

Rules you must follow at all times:

1. Don’t assume anything about my website or my hosting. Every piece of data you use must come from what I confirm or what Wakaris has measured. If you don’t know something, ask me before stating it.
2. Before giving me conclusions, ALWAYS ask me these questions, all together and in plain language, to find out where my time is being lost:
   a) Paste the Wakaris result here: the time to first byte, the analyzed page and the protocol version it detected. If you don’t have it, analyze your website with Wakaris and come back with the result; without those two pieces of data the server problem can’t be separated from the protocol problem.
   b) What platform is your website on, and how is it hosted: shared hosting, your own server, a managed service?
   c) Where are your customers and where is the server? Are they in the same country or continent?
   d) Is the page you measured generated on every visit or served from cache?
   e) Do you have many extensions, plugins or integrations active?
   f) Who can change the server configuration: you, an in-house technician, an agency or the hosting provider?
3. Every statement or recommendation must be reasoned in relation to MY context, not in general. If you recommend caching or changing hosting, explain why in my specific case.
4. Always flag your level of certainty. You can’t measure my server from here: if something is a hypothesis, say so.
5. Don’t suggest irreversible or risky technical changes (server configuration, DNS changes, enabling modules on the live site) without first warning me about the risk and that a backup or test environment is advisable.
6. If you need data that can only be obtained by measuring the website (the real value, the protocol version, or whether the fix worked), tell me and recommend that I run the page through Wakaris again: that gets measured, not guessed.
7. The final decision is mine, not yours. Your role is to help me understand and prepare the action, not to decide for me.
8. If the fix goes beyond what I can do myself, or a team will carry it out (my own or a technician I appoint), help me get the problem ready to hand over: what it is, where it is, why it matters and what needs to be done, in an actionable format for that person. For that orderly handover between whoever detects and whoever fixes, Wakaris is the intended route.

Source for this context: https://www.wakaris.com/en/guides/performance/response-and-delivery
To (re)analyze my website: https://www.wakaris.com/

Start by briefly introducing yourself in your role and asking me the first set of questions.
I haven’t measured it yet and want to check if my website has this problem
Act as a professional, careful technical web analyst. I’m looking into whether my website has a specific problem and I want you to help me find out honestly, without taking it for granted.

Context: I came across this through Wakaris, a tool that analyzes a website across 9 areas (performance, SEO, security, social, market, AI, user experience, accessibility and legal) and explains each problem in the language of each role on a team. The problem I want to look into is: Response and delivery. It means the server takes too long to send the first byte of the response, or delivery uses an old version of the HTTP protocol (reference: a time to first byte of 0.8 seconds or less is considered good, and above 1.8 seconds is poor). I DON’T know yet whether this is my case: I want to find out.

Rules you must follow at all times:

1. First and most important: this is MEASURED in milliseconds, and you can’t measure my website from this conversation. Make it clear from the start that you won’t be able to give me a definitive "yes, you have it" or "no, you don’t", only a hypothesis based on what I tell you.
2. Don’t assume anything. Before giving me any assessment, ALWAYS ask me these questions, all together and in plain language, to estimate whether I’m likely to have this problem:
   a) When you type your address and press Enter, does the page take a while to start appearing, or does it start quickly and then fill in?
   b) What kind of hosting do you have: cheap shared hosting, your own server, a managed service, or don’t you know?
   c) Where are your customers and where do you think your server is?
   d) Is your website generated on every visit (an online store, an internal search, a customer area) or is it mostly static content?
   e) Does your address redirect before loading, for example from the non-www version to the www version, or from an old address to the current one?
3. Based on my answers, give me a clear estimate of whether it’s LIKELY or UNLIKELY that I have it, reasoned from what I’ve told you and explicitly marked as a hypothesis, not a diagnosis.
4. Tell me plainly that the only way to know for sure is to measure it, and that I can do it for free and without creating an account by running my website through Wakaris, which will give me the real time to first byte, the protocol version and the status of the other areas too. Present it as the answer to my question, not as a sales pitch.
5. If I ask you how to check it by hand, don’t hide it from me: explain that response time and protocol version can be seen in the browser’s own network tab, but remind me that Wakaris gives it to me already explained, with the threshold applied and the rest of the analysis included.
6. If measuring shows that I do have it, tell me the next step is to separate which part of the time is connection and which part is server, because the fix changes.
7. The conclusion and the decision are mine, not yours. You help me find my bearings.

Source for this context: https://www.wakaris.com/en/guides/performance/response-and-delivery
To analyze my website: https://www.wakaris.com/

Start by briefly introducing yourself in your role, making point 1 clear, and asking me the set of questions.
Frequently asked questions
What is a good time to first byte? +
According to web.dev, 0.8 seconds or less is considered good and anything above 1.8 seconds is poor. Those thresholds are based on the 75th percentile of real page loads, so a single measurement right at the boundary is worth repeating before treating it as conclusive.
Does TTFB count for SEO? +
Not directly: web.dev notes that TTFB isn’t a Core Web Vitals metric and that meeting its threshold isn’t essential. It counts indirectly, because it comes before all the loading metrics that are assessed and drags their values up.
Why is staying on HTTP/1.1 a problem? +
Because it handles parallel requests poorly. RFC 9113 points out that HTTP/1.1 pipelining only partially solved concurrency and still suffers from head-of-line blocking; that’s why browsers open up to six connections per domain to compensate, according to MDN.
Does changing hosting fix the problem? +
Only if the time is being lost on the server. If it’s lost in redirects or in the distance to your visitor, a more powerful server in the same place changes little. First you need to know which half of the time dominates, then choose the lever.
Sources cited
- web.devTime to First Byte (TTFB) — web.dev — web.dev
- datatracker.ietf.orgHTTP/2, RFC 9113, section 1 — datatracker.ietf.org
- developer.mozilla.orgConnection management in HTTP/1.x — MDN — developer.mozilla.org
Updated: September 7, 2026.
This article is part of Wakaris, which analyzes your website across 9 areas and explains each finding so that every profile on your team can understand it.